Forecasting of the Traffic Situation in the Hannover Region
The main requirement of road traffic participants is to know the current traffic situation. Such data is typically obtained from routing services where the time of many different individual trips is taken into account.
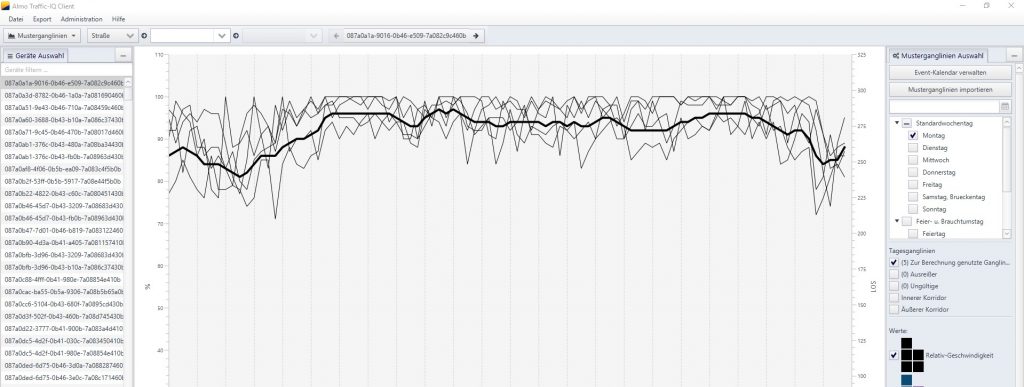
In the context of Data4UrbanMobility tools were developed that allow to predict the traffic situation based on such time series data. The following figure presents an interface to visualize typical time series patterns as well as outliers present in the data:
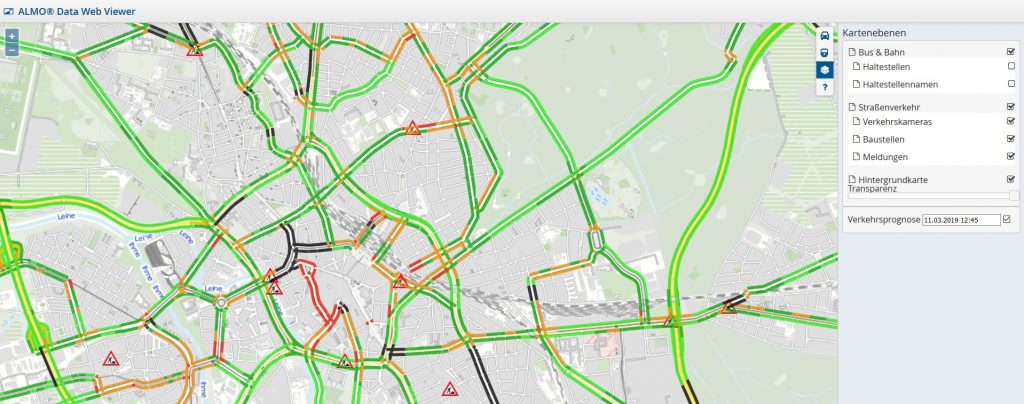
The prediction of the traffic situation is made available in the form of a map based interface for the end user:
Data4UrbanMobility Data Protection Regulation
The work on the Data4UrbanMobility data protection regulation is completed. The document is publicly available and can be found here.
First Version of MiC-App Available
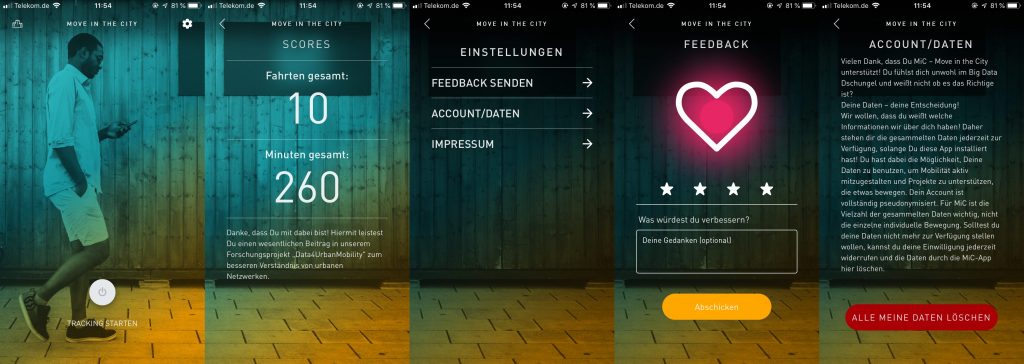
A first version of the novel MiC-App (Move in the City) App is now available for D4UM-associates as well as a protected group of public users. The mobile MiC-App is a tool to gather data.
MiC was developed by the Institute for Sustainable Urbanism at the University of Braunschweig and the Projektionisten GmbH. MiC links the growing awareness of digital citizen rights with the potential of evaluation big datasets. Therefore MiC gives the opportunity to citizen to actively participate in a citizen science project to take part in the development of the mobility of the feature.
MiC gathers data of the users movement, where the user has the about which data should be recorded. All data is pseudonymised such that the privacy of the contributing citizen is ensured.
Current Status:
In the first version of the app, the user can easily start and end the tracking of his/her movement. It is worth to point out, that the user decides when he is tracked and when not. A summary of his/her activity is available for the user as well as the opportunity to issue feedback or even delete all of his contributed data.
Updated System with Dashboard V2
With the new version of our system, the dashboard will provide even more insights into the impact of public events on the traffic situation.
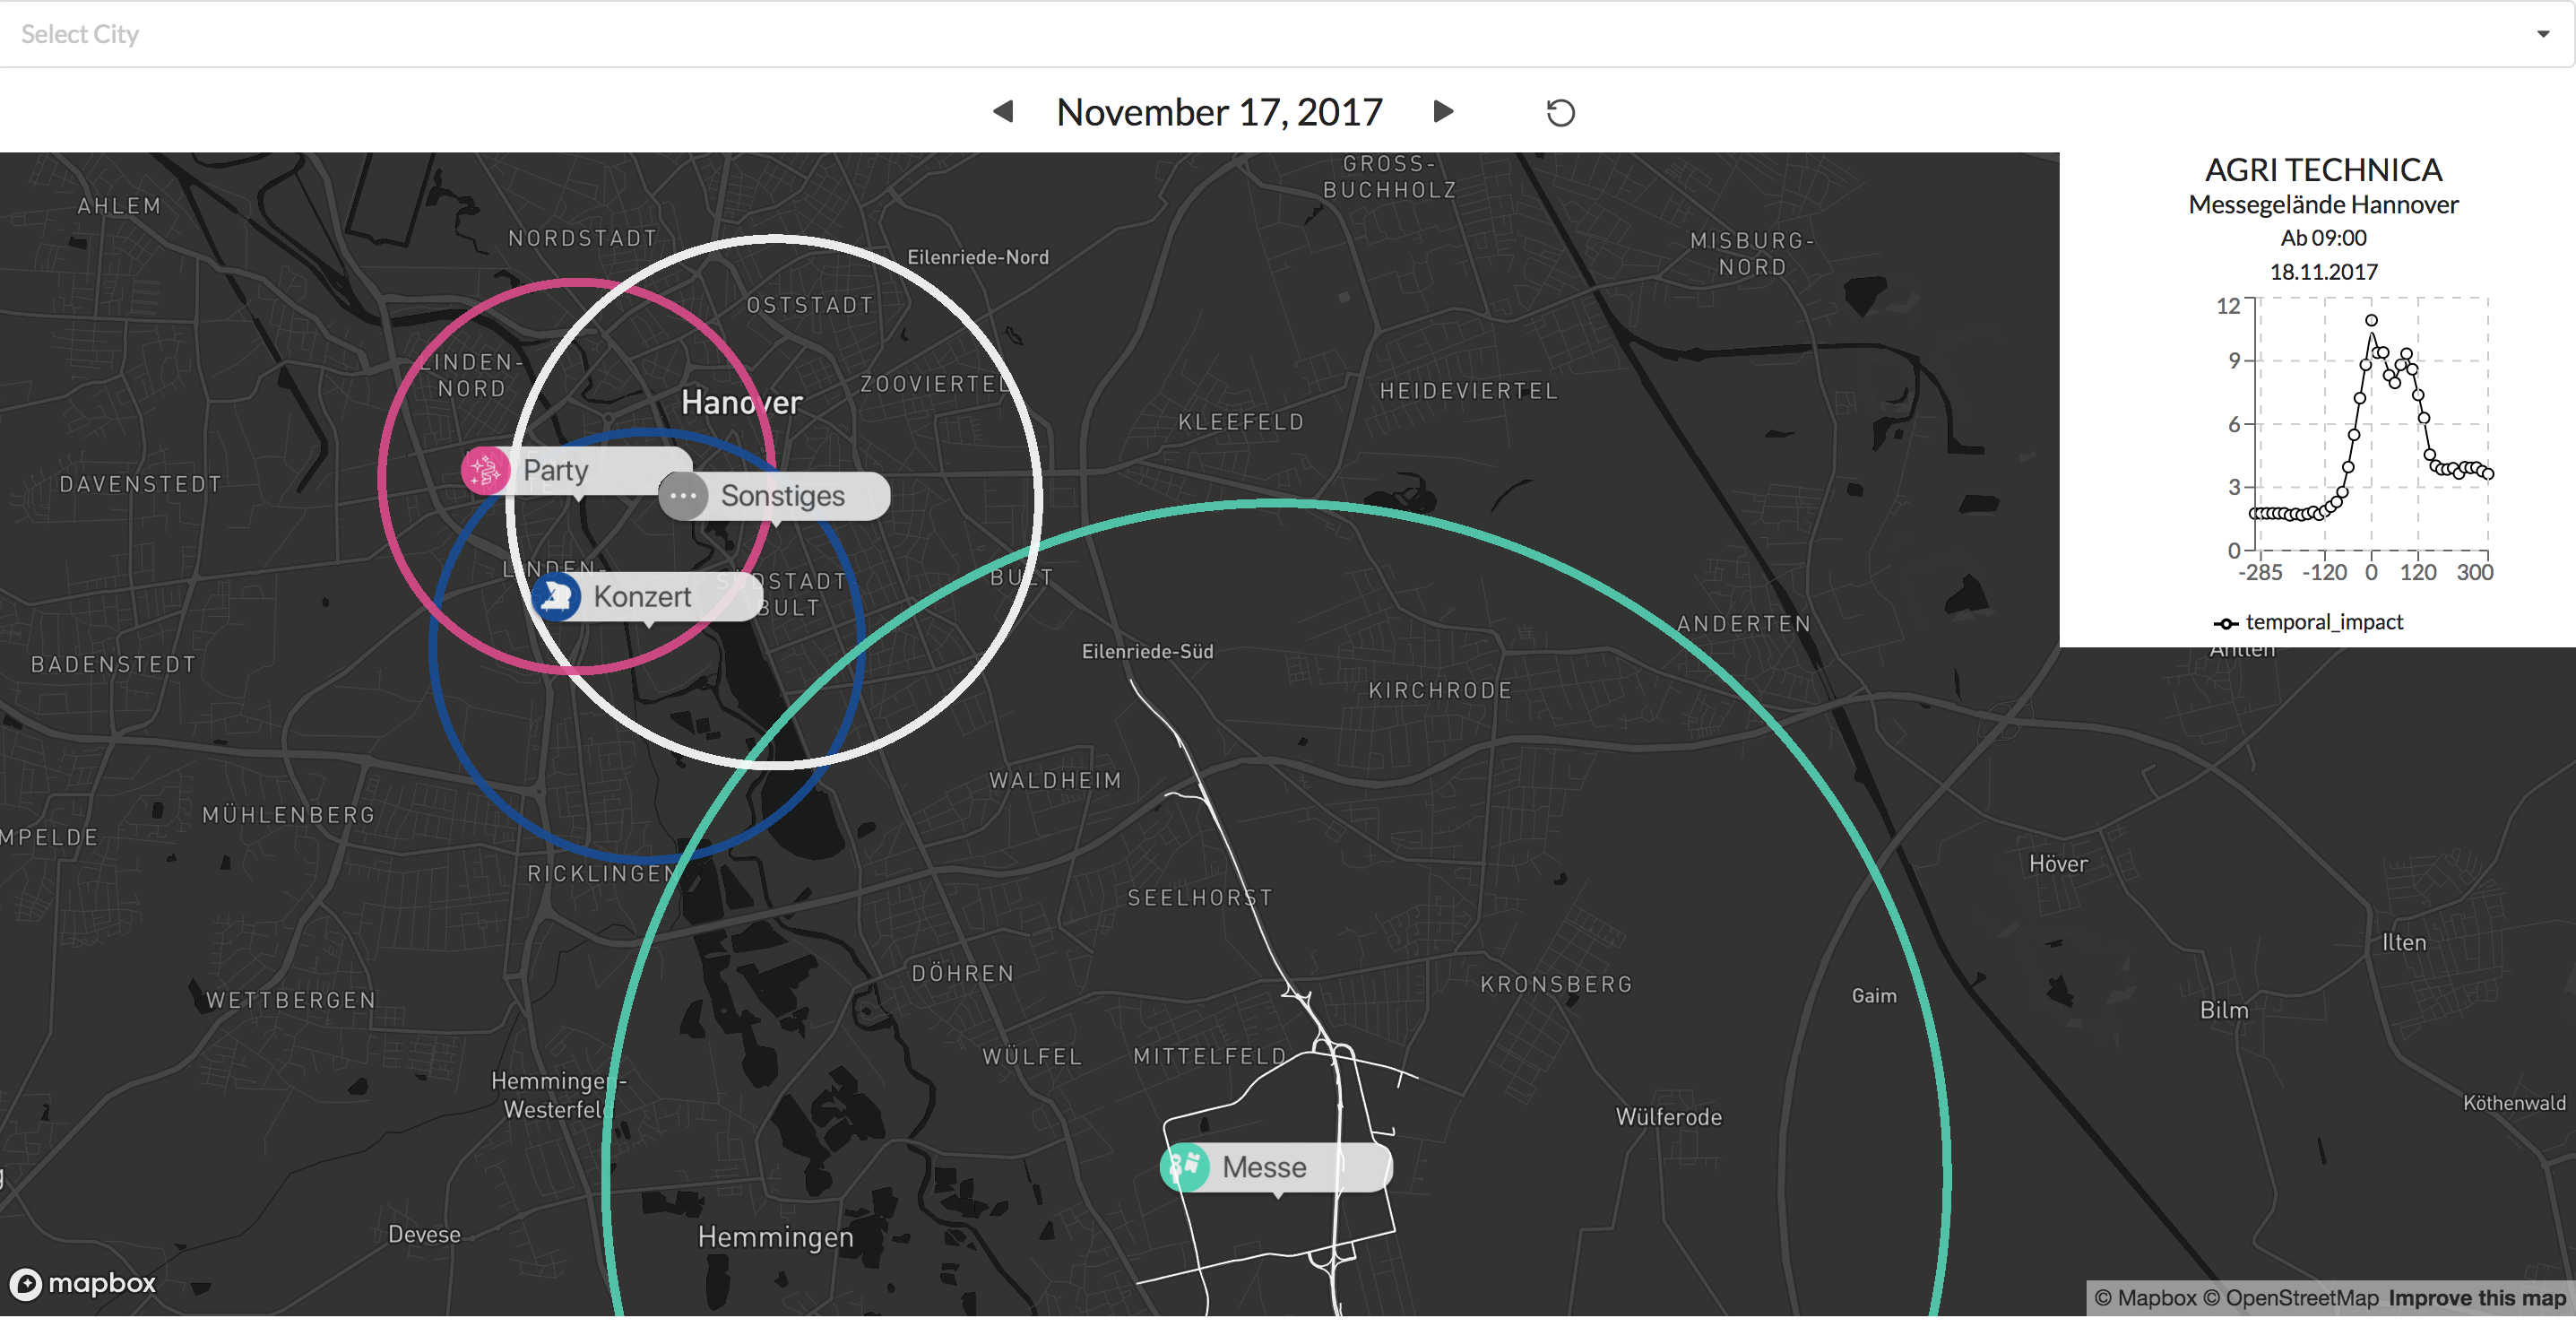
The coloring and labels let us easily distinguish between the different type of events. By clicking on the label we show the typically affected subgraph for that event type. This allows the user to check what specific routes are typically affected by an event at that location.
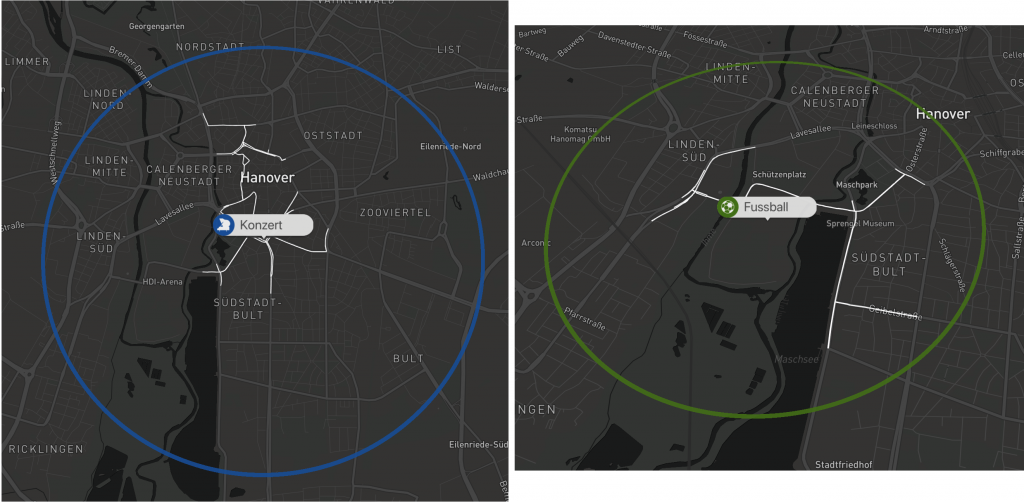
Examples: Visualisation of a concert and a football game.
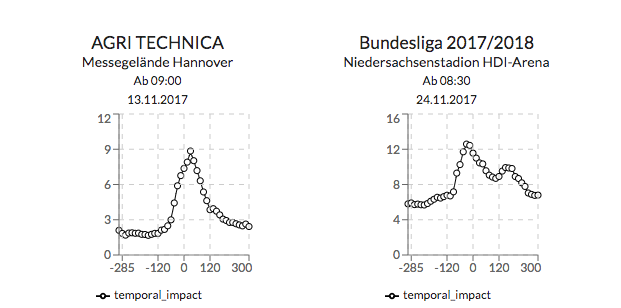
In addition, the graph at the top right gives additional information on how big the impact around the events start time tends to be.
{API}
We enriched the api endpoints with additional information from the data models that were developed as part of the research efforts.
D4UM App Version 1.0
We just released the first Version of the D4UM App. Every project member now has access to the application and can try out its features. Let’s quickly go over some of its main features.
The EFA integration (EFA is a routing engine covering Lower Saxony and Bremen ) allows for quick access to tip information using all available public transport options. Our focus, when designing the application, was on quick and easy navigation to provide a simple and easy to use trip planning tool.
Departures and Connections
On the departure screen we show the user the closes stops for public transportation in his immediate vicinity. On the connection screen the user can fill in his desired starting location( either an address or an existing stop ) and destination and query for what connections are available to him. The provided information contains real time data , meaning we are able to visualized delays for any given connection.
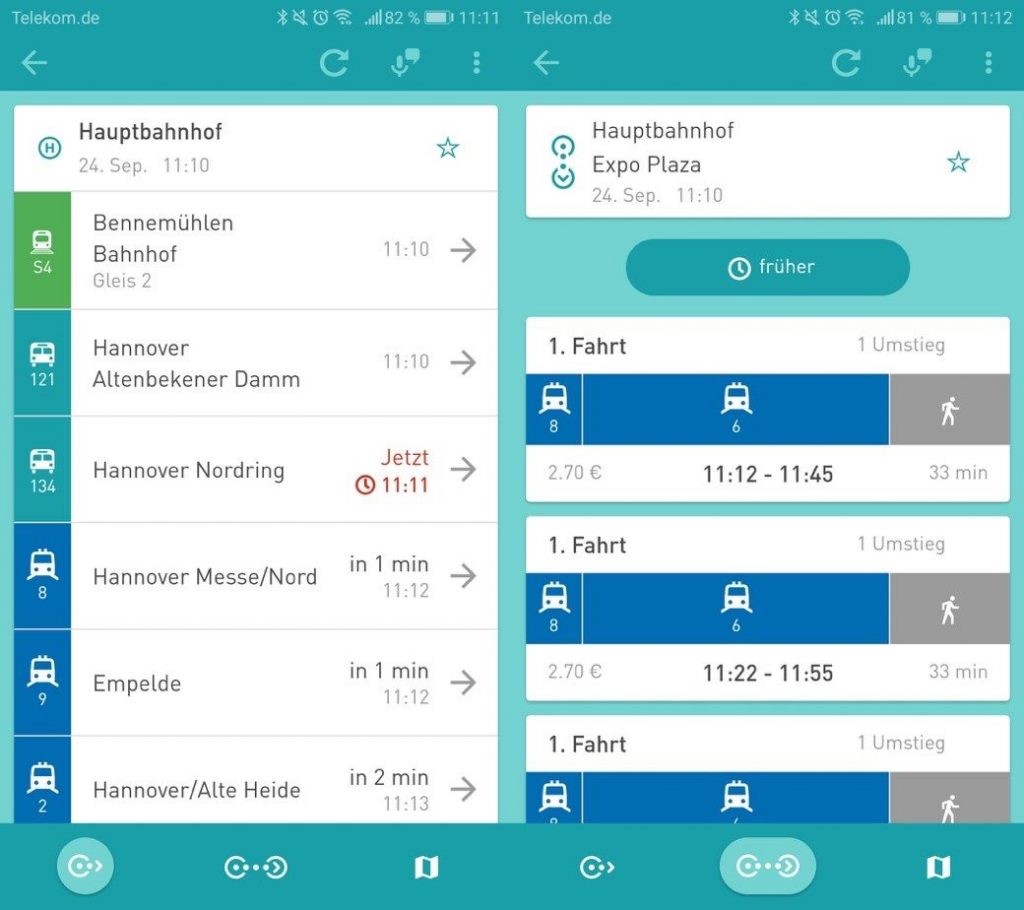
Map
On the map screen you can see and or find all available stops of public transportation. This allows for providing the user with a great way to find out what stops are available in their city. By clicking on any of the shown stops will open the departure screen and provide you with the information mentioned above. To better visualize a selected connection, we show the route you plan to travel on the map.
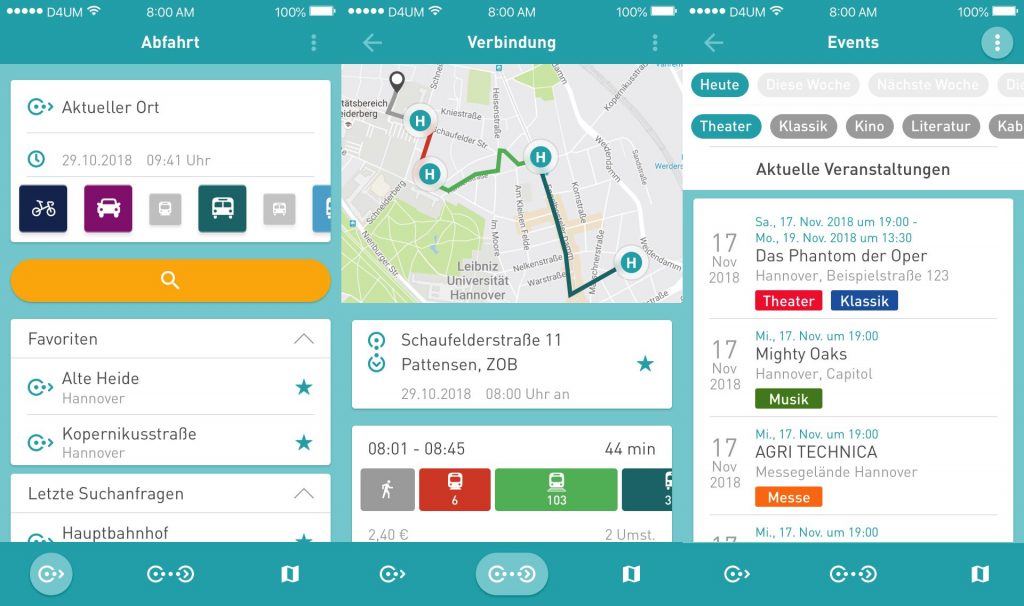
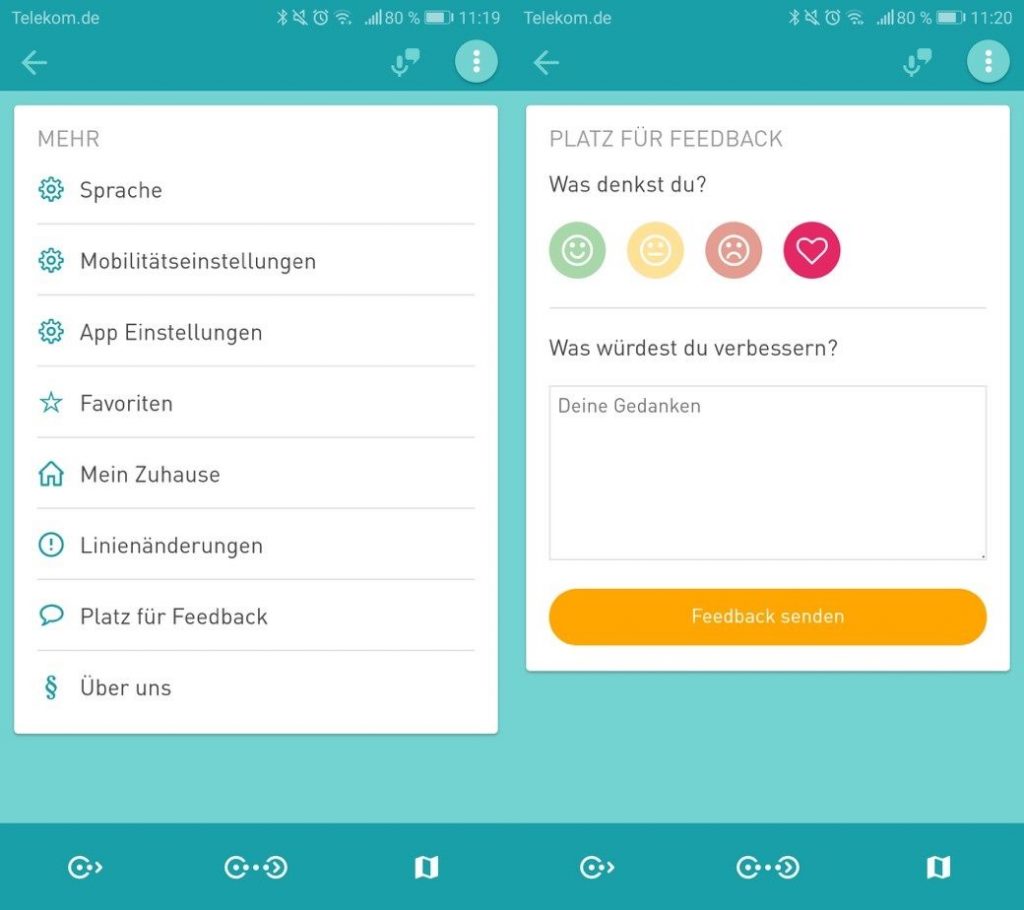
Menu / Settings
Additional features can be found in the settings menu of the application. Here you can find settings that allow you to customize your routing results for both the departures and connection screen. The best way to let us know what you think about the application is to use the feedback module. This can be found here as well. First click on the emoji that best describe how you feel about the app. And then put in any additional information or ideas or thoughts you may have. Now what is left is just to press send and you will send us an email.
We look forward to hearing from you.
Quantification and Prediction of Impact of Public Events
Current Data4UrbanMobility research results allow for measuring and prediction of spatial impact on road traffic of public events. Connected, affected street segments nearby public events are identified to measure the spatial impact. The approach is depicted in the following figure:
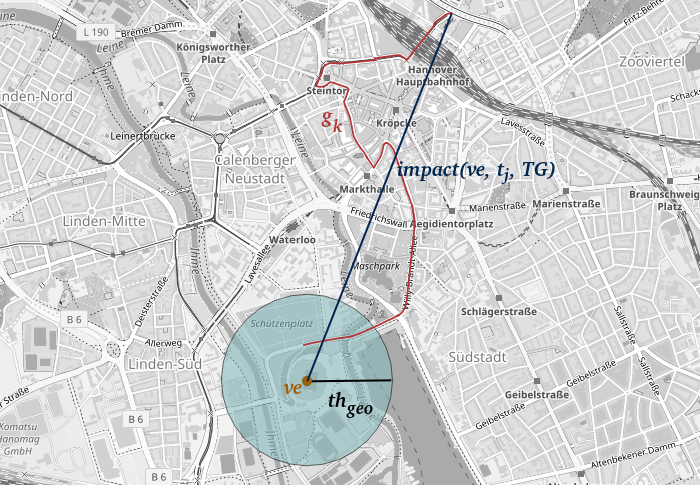
An event is marked as yellow dot, affected streets in red and the measured impact in dark blue. Moreover, an approach making use of machine learning algorithms was developed to predict the impact determined in this way, resulting an error-reduction of up to 40% when compared to existing state-of-the-art approaches.
D4UM – Platform V1 Released
The first version of the Data4UrbanMobiltiy platform has been released. The platform was designed and implemented following a 3-tier-architecture. The platform provides RESTfull Web services for mobility applications like dashboards or mobile apps. As a demonstration, an interactive map application has been developed that visualizes the spatial impact of public events. The following figure shows a screenshot of the application.
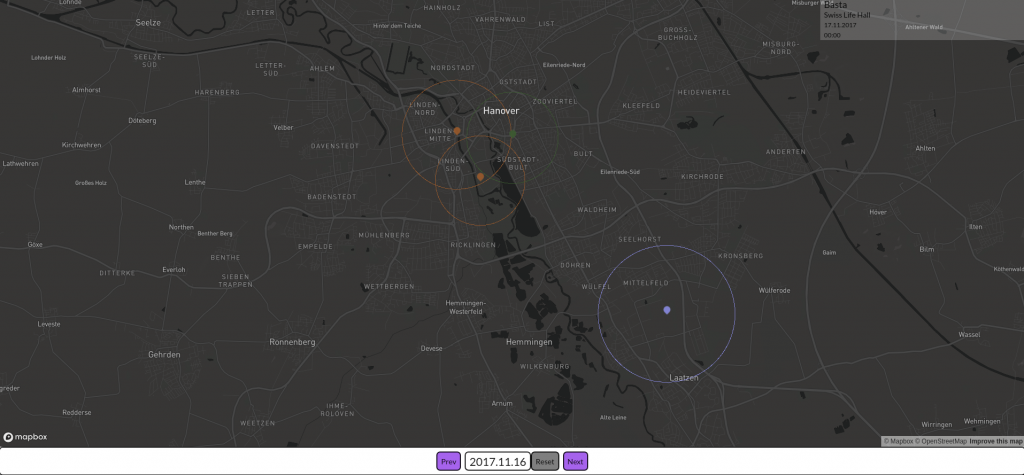
The figure shows 4 public events in the city of Hannover. The colors represent different types of public events (e.g. concerts, fairs, sport events). The circles visualize the spatial impact on road traffic caused by the public events.
Comprehensive Set of Requirements
The Data4UrbanMobility analysis of requirements includes requirements of the application partners Region Hannover (RH) and Wolfsburg AG (WAG) as well as non functional requirements. The requirements were collected by MOMA. The L3S derived research question for data analysis which are based on the requirements of RH and WAG. The research question address especially the information needs of end-users.
The current research questions particularly include
- Automated verification of traffic warnings and prediction of their impact
- Identification of events and prediction of their impact
- Investigation of correlation of road traffic data, public transportation query logs, traffic warnings and twitterfeeds
- Determination of optimal traveling timepoints
Growing Data Collection
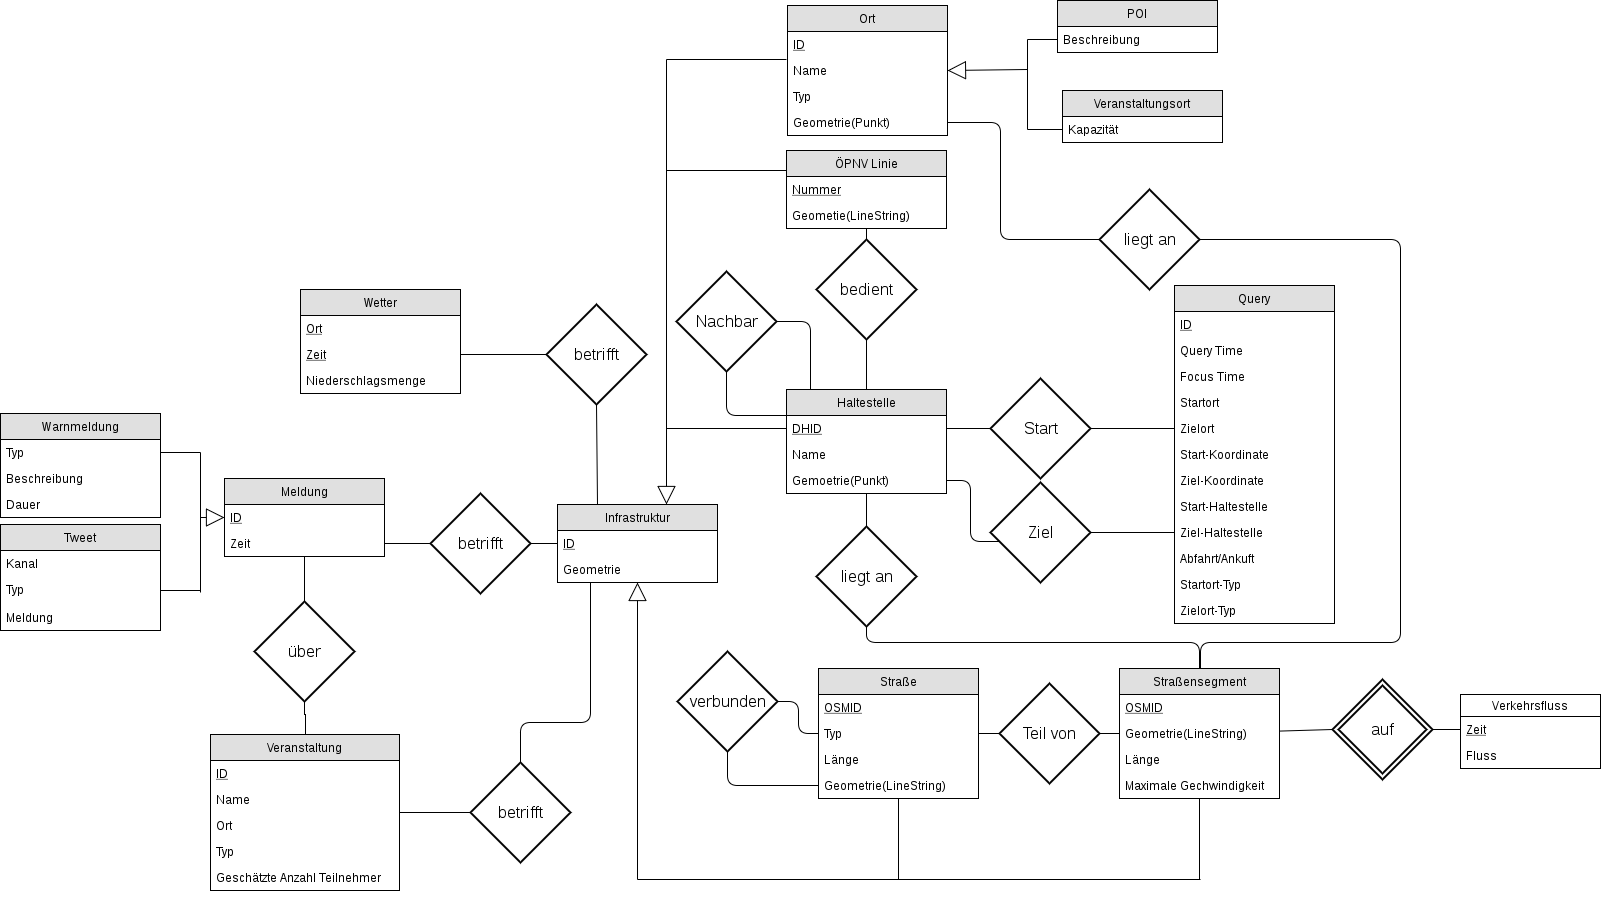
ISU create a comprehensive data matrix containing potential source of mobility related data. The Data4UrbanMobility data model describes all project relevant data sets and sets them into context. This makes the data available in a unified manor for both analysis and applications. The selected data sources were transformed according to the Data4UrbanMobility data model by L3S. The data quality of selected data sources (i.e. public transportation query logs and road traffic data) was examined.
Tools for extracting the relevant information from the datasets were developed to enable the integration of the datasets.
- Street and graph extraction from OpenStreetMap
- Bulkloader for public transportation queries
- Integration of “Zentrales Haltestellen Verzeichniss” (central registry of public transportation stops)
The current collection (December 12th 2017) contians
EFA-Logs: 17 million public transportation queries
Road traffic data: 174 thousand street sements with a frequency of 15 minutes
GTFS-data: 90 thousand. public transportation stops, 2.6 thousand routes
Weather: Radolan “Regenraster” (rain grid)
Twitter: 2,5 Mio. Tweets starting at June 2017
OSM: 440 thousand streets
Events: 21 thousand public events (August 14th 2016-July 17th 2018)
Traffic warnings: 13 thousand warning (since June 2017)
Visualization of Public Transportation Information
In order to allow intuitive analytics of public transportation information, the PROJEKTIONISTEN (PROJ) developed a dashboard web application. First prototypes visualize queries addressed to the regional timetable information system EFA (www.efa.de). The prototypes serve as foundations for exploration analyses as well as the implementation of future versions of the dashboard. The following figure shows an integrated visualization of the most frequent origins and destinations of the queries.
Analysen der EFA-Logs
Analysis of EFA Public Transportation Query Logs
Analyses regarding the impact of public events on public transportation are currently conducted to address early research questions. To this extend, explorative data analyses of the impact of major public events such as football games and medium sized events such as concerts were conducted. Visual analytics were used as a first step towards comprehensive analyses, which show start-like patterns for city center which identify mobility hubs of central importance.
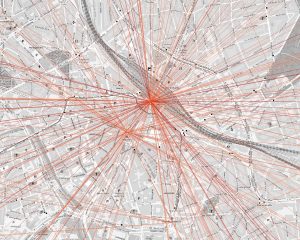
The figure shows the direct connection between origin and destination of public transportation queries. Darker colors correspond to more frequent queried trips. Star-like pattern identify the central train station and the central metro station.
Analyses of single stations reveal weekday dependent patterns.
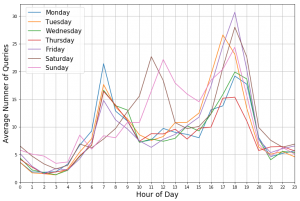
The figure depicts the average number of queries with the destination “Hannover Stadionbrücke”. Differences emerge between Weekends and workdays.
The impact of public events on the queries can be visualized as well.
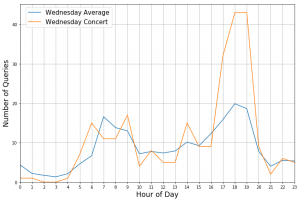
The figure shows the number of queries with the Destination “Hannover Stadionbrücke” for Wednesday, April 26th 2017 (orange) as well as the average number of queries on a Wednesday for the same destination. On this day a concert took place in venue nearby. The concert start at 8 pm. The significant deviations between 5 pm and 7 pm is highly likely to be caused by visitors of the concert. This shows that public transportation queries are a valuable information source to investigate the impact of public events on mobility infrastructure.
Towards a Multi-Agent LLM-Based Tutoring Tool for Mathematical Argumentation Skills. Koulani, Huda; Marchionne, Lucia; Schmidtpott-Schulz, Hendrikje; Eichler, Andreas; Bley, Andreas; Söllner, Matthias in Lecture Notes in Computer Science (2026). (Vol. 16607) 68–79.
Mathematical argumentation is a core competence that integrates mathematical reasoning with broader critical thinking skills, enabling students to construct coherent and logically structured arguments to evaluate mathematical claims. This skill is essential for undergraduate students across disciplines such as information systems, mathematics, and computer science—yet many struggle to develop it. Recent advances in Large Language Models (LLMs) and multi-agent systems offer a promising opportunity to address these challenges by supporting students in refining their mathematical argumentation within a tutorial setting. In this Research-in-Progress paper, we adopt a Design Science Research approach to generate design knowledge for an LLM-based tutoring tool aimed at fostering students’ argumentation skills. Drawing on user requirements and meta-requirements derived from user interviews and theoretical foundations, we derive four design principles and propose a prototype of a multi-agent LLM-based tutoring tool. The system delivers formative feedback on students’ proofs and provides tutorial guidance through step-by-step explanations, grounded in theories of formative feedback and tutorial guidance.
Sparse Linear Algebra Accelerates Genotype Representation Graph Computation at Biobank Scale. Li, Yifan; Sun, Qingyao; DeHaas, Drew; Zhao, Max Xiaohang; Boyko, Adam R.; Musharoff, Shaila A.; Wei, Xinzhu; Guidi, Giulia (2026).
Biobank-scale genomic analyses are increasingly constrained by computational costs, as hundreds of thousands to millions of samples and variants must be analyzed together. The genotype representation graph (GRG) compactly encodes population genetic variation to accelerate computation, but the current approach does not exploit modern accelerator architectures. This work introduces Mikado, a new methodology for expressing GRG-based computation, previously performed by graph traversal, using sparse linear algebra primitives. Under a reverse topological ordering of the graph nodes, the GRG adjacency matrix is strictly block-lower-triangular, and the genotype matrix-vector product becomes a sparse triangular solve that can be further decomposed into a pipelined sequence of blocked sparse matrix-vector multiplies. By decoupling computation from graph representation, our approach exposes fine-grained parallelism and enables hardware-optimized sparse primitives on GPUs. Mikado achieves an order-of-magnitude speedup and cost savings for PCA and BOLT-LMM compared with the original GRG traversal approach, including on All of Us cohorts. It provides a scalable, hardware-portable, researcher-friendly tool for population genetics at biobank scale.Competing Interest StatementThe authors have declared no competing interest.NSF, IIS-243580NIH, R35-GM150579
Are urban form and function related to urban discourse? Insights from remote sensing and social media data for 15 major cities across the globe. Jheng, De-Cyuan; Lemoine-Rodríguez, Richard; Biewer, Carolin; Seto, Karen C.; Taubenböck, Hannes (2026). 175 103907.
From Measured to Experienced Heat: A Multimodal Analysis of Temperature, Urban Form, and Social Media in Mexico City. Lemoine-Rodriguez, Richard; Debray, Henri; Biewer, Carolin; Inostroza, Luis; Taubenbock, Hannes (2026). 19 30044–30056.
Joint efforts for a green future: Evaluation on Finland’s development cooperation in environment and sustainable use of natural resources, and private sector opportunities Laaksonen, S; Caldecott, J; Olding, W; Mikkola, K; Savage, M; Tommila, P; Nieminen, A; Lemoine-Rodríguez, R (2026). Ministry for Foreign Affairs of Finland.
Spatio-temporal and Linguistic Assessments of Urban Space: Applications, Implications and Outlook. Biewer, C; Lehnen, L; Lemoine-Rodríguez, R; Schulz, N; Taubenböck, H C. Biewer, L. Lehnen, N. Schulz, H. Taubenböck (eds.) (2026). 410–422.
Imagined Communities on Social Media: Exploring Linguistic Othering during Brexit. Elliott, Z; Lemoine-Rodríguez, R C. Biewer, L. Lehnen, N. Schulz, H. Taubenböck (eds.) (2026). 218–245.
Exploring Twitter Discourse across Different Districts of Edinburgh during the COVID-19 Pandemic. Schulz, N; Lemoine-Rodríguez, R C. Biewer, L. Lehnen, N. Schulz, H. Taubenböck (eds.) (2026). 326–371.
Using Geolocated Social Media Data to Characterise the Socio-spatial Dimension of Cities: A Case Study on Tweets from New York. Lemoine-Rodríguez, R; Biewer, C; Mast, J; Taubenböck, H C. Biewer, L. Lehnen, N. Schulz, H. Taubenböck (eds.) (2026). 285–325.
Population-scale Ancestral Recombination Graphs with tskit 1.0. Jeffery, Ben; Wong, Yan; Thornton, Kevin; Tsambos, Georgia; Bisschop, Gertjan; Deng, Yun; Ellerman, E. Castedo; Forest, Thomas B.; Fritze, Halley; Goldstein, Daniel; Gorjanc, Gregor; Gower, Graham; Gravel, Simon; Guez, Jeremy; Haller, Benjamin C.; Kern, Andrew D.; Kirk, Lloyd; Krukov, Ivan; Lee, Hanbin; Lehmann, Brieuc; Loay, Hossameldin; Osmond, Matthew M.; Palmer, Duncan S.; Pope, Nathaniel S.; Ragsdale, Aaron P.; Robertson, Duncan; Rodrigues, Murillo F.; van Kemenade, Hugo; Weiß, Clemens L.; Wohns, Anthony Wilder; Zhan, Shing H.; Zhang, Brian C.; Aspbury, Marianne; Baya, Nikolas A.; Belsare, Saurabh; Biddanda, Arjun; Jiménez, Francisco Campuzano; Gladstein, Ariella; Guo, Bing; Karthikeyan, Savita; Kretzschmar, Warren W.; Rebollo, Inés; Saunack, Kumar; Shemirani, Ruhollah; Simon, Alexis; Smith, Chris; Sukumaran, Jeet; Terhorst, Jonathan; Unneberg, Per; Zhang, Ao; Ralph, Peter; Kelleher, Jerome (2026).
Ancestral recombination graphs (ARGs) are an increasingly important component of population and statistical genetics. The tskit library has become key infrastructure for the field, providing an expressive and general representation of ARGs together with a suite of efficient fundamental operations. In this note, we announce tskit version 1.0, describe its underlying rationale, and document its stability guarantees. These guarantees provide a foundation for durable computational artefacts and support long-term reproducibility of code and analyses.
Genetic prediction with ARG-powered linear algebra. Lee, Hanbin; Pope, Nathaniel S; Kelleher, Jerome; Gorjanc, Gregor; Ralph, Peter L (2026). 233(1) iyag074.
Ancestral recombination graphs (ARGs) are an attractive means for quantitative genetic analysis of complex traits because they encode the realized genetic relatedness between a sample of individuals in the presence of genetic drift, recombination, and mutation. Data structures for efficiently storing ARGs can also be used to rapidly process millions of genomes, and are thus promising for fitting linear mixed models to large phenotype and genome datasets. Here, we study the problems of variance component estimation and prediction of genetic values with ARGs, by describing a generative model of complex traits with additive effects on an ARG, and then developing algorithms that use the ARG to solve these problems efficiently on biobank-scale datasets. We observe nearly linear scaling of runtime with sample size, which is achieved by using the succinct tree sequence representation of the ARG for implicit matrix-vector products, along with modern randomized linear algebra algorithms. We estimate variance components using restricted maximum likelihood, which we find performs substantially better than the Haseman–Elston method. In simulation tests, both variance component estimation and prediction of genetic values (using the best linear unbiased predictor) perform nearly as well with inferred ARGs as with true ARGs. We also discuss interpretations of the variance component estimates as mutational variance and additive genetic variance. We provide an implementation of the algorithms as a Python package tslmm, which leverages the tree sequence library tskit.
Does NDVI explain patterns of urban bird diversity? Insights from temperate to tropical cities. MacGregor-Fors, Ian; Garizábal-Carmona, Jaime A.; García-Arroyo, Michelle; Fishel, Eric; Nilon, Charles H.; Lemoine-Rodríguez, Richard (2026). 116 129211.
A forest is more than its trees: haplotypes and ancestral recombination graphs. Fritze, Halley; Pope, Nathaniel; Kelleher, Jerome; Ralph, Peter (2026). 232(1) iyaf198.
Foreshadowing haplotype-based methods of the genomics era, it is an old observation that the “junction” between two distinct haplotypes produced by recombination is inherited as a Mendelian marker. In a genealogical context, this recombination-mediated information reflects the persistence of ancestral haplotypes across local genealogical trees in which they do not represent coalescences. We show how these non-coalescing haplotypes (“locally-unary nodes”) may be inserted into ancestral recombination graphs, a compact but information-rich data structure describing the genealogical relationships among recombinant sequences. The resulting ancestral recombination graphs are smaller, faster to compute with, and the additional ancestral information that is inserted is nearly always correct where the initial ancestral recombination graph is correct. We provide efficient algorithms to infer locally-unary nodes within existing ancestral recombination graphs, and explore some consequences for ancestral recombination graphs inferred from real data. To do this, we introduce new metrics of agreement and disagreement between ancestral recombination graphs that, unlike previous methods, consider ancestral recombination graphs as describing relationships between haplotypes rather than just a collection of trees.
Tracing the evolutionary histories of ultra-rare variants using variational dating of large ancestral recombination graphs. Pope, Nathaniel S.; Tallman, Sam; Jeffery, Ben; Robertson, Duncan; Wong, Yan; Karthikeyan, Savita; Ralph, Peter L.; Kelleher, Jerome (2026).
Ultra-rare variants dominate whole-genome sequencing datasets, yet their interpretation is limited by allele frequency, which provides little information at very low counts and is highly sensitive to uneven ancestry representation. Allele age offers an ancestry-agnostic alternative but existing methods do not scale to biobank-sized cohorts. Here we present a scalable variational algorithm for dating Ancestral Recombination Graphs (ARGs), imple- mented in tsdate, together with new distributed methods enabling practical biobank-scale ARG inference using tsinfer. Applied to 47,535 genomes from the Genomics England 100,000 Genomes Project, we infer contiguous ARGs spanning 206 Mb and estimate ages for 23.2 million variants, including 11.8 million singletons. ARG-based allele ages remain accurate under extreme sampling imbalance and, in real data, reveal signatures of purifying selection and clinically relevant heterogeneity among variants with identical observed frequencies. Estimates for recent mutations are precise only at large sample sizes, highlighting the infor- mation accessible in the haplotype structure of large datasets. Biobank-scale ARGs therefore enable robust, ancestry-agnostic age estimation for ultra-rare variation with broad utility for statistical and clinical genomics.
Likelihoods for a general class of ARGs under the SMC. Bisschop, Gertjan; Kelleher, Jerome; Ralph, Peter (2026). 232(1) iyaf103.
Ancestral recombination graphs (ARGs) are the focus of much ongoing research interest. Recent progress in inference has made ARG-based approaches feasible across of range of applications, and many new methods using inferred ARGs as input have appeared. This progress on the long-standing problem of ARG inference has proceeded in two distinct directions. First, the Bayesian inference of ARGs under the Sequentially Markov Coalescent (SMC), is now practical for tens-to-hundreds of samples. Second, approximate models and heuristics can now scale to sample sizes two to three orders of magnitude larger. Although these heuristic methods are reasonably accurate under many metrics, one significant drawback is that the ARGs they estimate do not have the topological properties required to compute a likelihood under models such as the SMC under present-day formulations. In particular, heuristic inference methods typically do not estimate precise details about recombination events, which are currently required to compute a likelihood. In this article, we present a backwards-time formulation of the SMC (conventionally regarded as an along-the-genome process) and derive a straightforward definition of the likelihood of a general class of ARG under this model. We show that this formulation does not require precise details of recombination events to be estimated, and is robust to the presence of polytomies. We discuss the possibilities for ARG inference that this new formulation opens.
Neural posterior estimation for population genetics. Min, Jiseon; Ning, Yuxin; Pope, Nathaniel S; Baumdicker, Franz; Kern, Andrew D (2026). 233(3) iyag107.
Simulation-based inference methods are increasingly being used in population genetics due to their flexibility and ability to be applied in settings where likelihood-based methods are intractable. Perhaps the best known such method is Approximate Bayesian Computation (ABC); however, its popularity is offset by its shortcomings which include computational expense and an unfortunate inability to efficiently fit models to high-dimensional summaries of the data. An alternative approach that solves these issues is supervised machine learning (ML); however, ML methods generally do not yield Bayesian uncertainty estimates of the quantities they predict. Here, we apply a recently introduced method, neural posterior estimation, that combines the best facets of ABC and supervised ML by training a neural network to estimate the posterior distribution of a population genetics model. We first compare neural posterior estimation with other inference methods for a variety of population genetic tasks, and show that neural posterior estimators yield posterior distributions with high accuracy and efficiency. We compare learned posterior distributions given raw genotypes and various summary statistics as input data. Additionally, we apply neural posterior estimation for demographic inference for simple and more complex models to highlight its application, including an analysis of demographic history in Drosophila melanogaster. Finally, we provide a user friendly workflow that enables others to perform neural posterior estimation on their own genetic data.
Simulation-Based Spatially Explicit Close-Kin Mark–Recapture. Patterson, Gilia; Goodfellow, Claire K.; Ting, Nelson; Kern, Andrew D.; Ralph, Peter L. (2026). 26(1) e70074.
ABSTRACT Estimating the size of wild populations is a critical priority for ecologists and conservation biologists, but tools to do so are often labour intensive and expensive. A promising set of newer approaches are based on genetic data, which can be cheaper to obtain and less invasive than information from more direct observation. One of these approaches is close-kin mark-recapture (CKMR), a type of method that uses genetic data to identify kin pairs and estimates population size from these pairs. Although CKMR methods are promising, one limitation to using them more broadly is a lack of CKMR models that can deal with spatially structured populations and spatial heterogeneity in sampling. In this paper, we introduce a spatially explicit approach to CKMR that uses individual-based simulation in concert with a deep convolutional neural network to estimate population sizes. Using simulations, we show that our method, CKMRnn, is highly accurate, even in the face of spatial heterogeneity in sampling and spatial population structure, and demonstrate that it can account for potential confounders such as unknown population histories. Finally, to demonstrate the accuracy of our method in an empirical system, we apply CKMRnn to data from a Ugandan elephant population, and show that point estimates from our method recapitulate those from traditional estimators but that the confidence interval on our estimator is approximately 30% narrower.
Global patterns in plant--pollinator specialization. Sakhalkar, Sailee P.; Blüthgen, Nico; Burkle, Laura A.; CaraDonna, Paul; Dalsgaard, Bo; Dormann, Carsten F.; Kaiser-Bunbury, Christopher N.; Knight, Tiffany M.; Ollerton, Jeff; Resasco, Julian; Schleuning, Matthias; Vázquez, Diego P.; Afagwu, Rita N.; Alarcón, Ruben; Amorim, Felipe W.; Amorim, Marsal D.; Anýž, Dominik; Arroyo-Correa, Blanca; Artamendi, Maddi; Atalay, Zeynep; Bain, Justin A.; Baldock, Katherine C. R.; Ballantyne, Gavin; Ballarin, Caio S.; Balmaki, Behnaz; Bartoš, Michael; Belavadi, Vasuki; Biella, Paolo; Bjorkman, Anne D.; Raimundo Borges, João Paulo; Bosch, Jordi; Bosenbecker, Camila; Boyer, Stephane; Burghardt, Karin T.; Cardona, Edson; Casiá-Ajché, Quebin Bosbely; Castagna, Anthony M. T.; Celep, Ferhat; Chisté, Melanie N.; Clough, Yann; Cook, James M.; Crowther, Liam P.; Reis, Fabiana D.; da Silva, Luis P.; Dáttilo, Wesley; De Cárdenas, Valeska; Díaz-Calafat, Joan; Dicks, Lynn V.; Dickson, Rye; Donald, Marion L.; Dyer, Lee A.; Dzekashu, Fairo F.; Escobedo Kenefic, Natalia; Fayle, Tom M.; Figueroa, Laura L.; Filip, Jan; García-Camacho, Raúl; Gilpin, Amy-Marie; Giménez-Benavides, Luis; Gomes, Ingrid N.; Grab, Heather; Grass, Ingo; Guy, Travis J.; Hederström, Veronica; Hernández-Castellano, Carlos; Hervías-Parejo, Sandra; Holzschuh, Andrea; Hopfenmüller, Sebastian; Iriondo, José M.; Janeček, Štěpán; Jersáková, Jana; Jha, Shalene; Kantsa, Aphrodite; Keasar, Tamar; Kendall, Liam; Klomberg, Yannick; Kobe, Ishmeal N.; Krausl, Theresia; Landaverde, Patricia; Lara-Romero, Carlos; Lattorff, H. Michael G.; Librán-Embid, Felipe; Ling, Tial C.; Lozada-Gobilard, Sissi; Luma, Francis Ewome; Luna, Pedro; Aguiar, Ludmilla M. S.; Pereira Machado, Ana Carolina; Machado, Isabel C.; Magrach, Ainhoa; Maihoff, Fabienne; Marcacci, Gabriel; Martínez-Núñez, Carlos; Maruyama, Pietro K.; Matsubara, Natsuki; Mayberry, Maggie; Mello, Marco A. R.; Mendes Diniz, Ugo; Méndez, Marcos; Mertens, Jan E. J.; Milla, Rubén; Morente-López, Javier; Nadia, Tarcila L.; Nakas, Georgios; Nielsen, Anders; Ornai, Alon; Osorio-Canadas, Sergio; Osterman, Wilhelm H. A.; Palmer, Todd M.; Petanidou, Theodora; Pirk, Christian W. W.; Prendergast, Kit S.; Primack, Richard; Primo, Luis M.; Querejeta, Marina; Quirino, Zelma; Rodrigo Rech, André; Reverté, Sara; Rey, Pedro J.; Rocha-Filho, Léo C.; Rodrigo Domínguez, Anselm; Rostami, Masoud A.; Russell, Avery L.; Santamaría, Silvia; Santos, Francisco A. R.; Sasaki, Takehiro; Saunders, Manu E.; Silva, Victor H. D.; Simanonok, Michael P.; Sounapoglou, Antigoni; Steffan-Dewenter, Ingolf; Tarrant, Sam; Torices, Rubén; Traveset, Anna; Tscharntke, Teja; Uceda-Gómez, Guillermo; Urban-Mead, Katherine R.; van der Kooi, Casper J.; Westphal, Catrin; Yusuf, Abdullahi; Tropek, Robert (2026).
Pollination is a key ecological process sustaining biodiversity and food security, yet global patterns of plant--pollinator specialization remain unresolved. Using a global dataset of quantitative plant--pollinator networks (>3,400 networks, >110,000 interactions), we show that specialization is latitudinally structured, but not as a single directional pattern. We find no consistent monotonic increase or decrease in specialization towards the Equator. Instead, network-level and pollinator specialization peak at low northern latitudes near the tropical--subtropical boundary, whereas plant specialization is hemispherically asymmetric. Climate is most often the best-supported predictor of specialization compared with latitude, biodiversity and environmental productivity. Network-level specialization declines with increasing mean annual temperature, with strong group-specific differences. Precipitation exerts nonlinear effects: plant specialization peaks at intermediate precipitation but is lower at the wettest sites, whereas pollinator specialization is lower at intermediate precipitation, although often in interaction with temperature. Pollinator groups diverge strongly, especially in contrasting precipitation-related patterns between birds and insects. These findings show that global plant--pollinator specialization is structured by latitude and climate in complex and taxon-specific ways, with implications for uneven responses of pollination networks to future climatic change.
Communal Weaving for a Carrier Bag Practice of Computing. Bläsing, Lisa Marie; Horn, Viktoria; Klumbyte, Goda; Lackner, Konstantin; Stöter, Lea; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–3.
Communal Weaving for a Carrier Bag Practice of Computing. Bläsing, Lisa Marie; Horn, Viktoria; Klumbyte, Goda; Lackner, Konstantin; Stöter, Lea; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–3.
Integrating Corpus Linguistics and NLP Methods to Explore Social Media Discourse from Edinburgh and London. Lehnen, Lisa; Schulz, Ninja; Lemoine-Rodríguez, Richard; Taubenböck, Hannes; Biewer, Carolin (2026). 4(1) 115–142.
ScrubPIM: Exploiting PIM to Enable In-Memory Error Correction. Christ, Derek; Reith, Tino; Wilbert, Nils; Jung, Matthias (2026). (Vol. 2)
Shifting Stories of Human-Centered Computing Research: Exploring Narratives Through the Lens of Le Guin’s The Carrier Bag Theory of Fiction. Horn, Viktoria; Stöter, Lea; Bläsing, Lisa Marie; Klumbyte, Goda; Lackner, Konstantin; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–4.
Response of endemic lizard populations to attempted eradication of invasive predators on a Galápagos island. Kumar, Kirtana; Dawson, Jeff; Digby, Roland; Espín, Alejandra; Escobar, Marcelo Gavilanes; Carrión, Victor; Reyes, Enzo Rodríguez; Rothacher, Julia; Huszarik, Maike; Sevilla, Christian; Schaefer, Martin; Müller, Jörg (2026). 63(9)
Design and Evaluation of an Adaptive Reading Support System for Comprehension. Hänel, Martin; Mwaita, Kevin Fred; Wambsganss, Thiemo; Söllner, Matthias (2026).
Reading complex informational text is essential for comprehending global scientific knowledge, yet many nonnative readers from practice-oriented pathways struggle to comprehend such materials and require adaptive support that existing systems do not provide. However, past research lacks prescriptive design knowledge on how to effectively design such support systems. Hence, we present results from our design science research endeavor to design and evaluate an adaptive reading support system grounded in comprehension theory. We built on design principles and instantiated them as adaptive hints and support functions typically scattered across separate tools. We evaluated the systems in an online experiment with 84 participants across three conditions: control, conversational interface, and canvas interface. The results show that a conversational interface grounded in ICAP improves comprehension, while canvas-based instantiations of prior design principles require careful design to manage their higher interaction complexity, illustrating how system design grounded in linguistic theory can support the processing of complex texts. The study contributes design knowledge for effective comprehension support systems.
Personalization of Information Systems: A Taxonomy and Research Agenda for Generative User Interfaces. Pott, Katja; Rietsche, Roman; Söllner, Matthias; Wambsganss, Thiemo (2026).
The novel paradigm of Generative user interfaces introduces a shift from predefined, static interfaces toward dynamically generated and contextually adaptive user experiences. While personalization in Information Systems (IS) is well established, it has largely focused on adapting content and functionality, whereas the user interface itself often remains predefined and static. Generative user interfaces address this limitation by leveraging generative artificial intelligence to generate front-end code, constructing and adapting interface components at runtime based on users’ needs, preferences, and context. This promises to not only enhance personalization but also disrupt current IS development. Yet, this emerging implementation raises fundamental questions for IS design and development. Although Generative user interfaces have recently attracted research interest in Human–Computer Interaction, there remains a lack of shared conceptual understanding of their design characteristics and implications for IS development. To address this gap, we develop a taxonomy that identifies these characteristics based on a Socio-Technical Systems perspective. We validate our taxonomy with experts and formulate a research agenda for Generative user interfaces, using the taxonomy as a conceptual foundation to guide future IS research.
What Does Pruning Actually Buy? Memory and Inference Time in Predictive Maintenance Models. Grillmeyer, Daniel; Turhal, Sükrü; Kounev, Samuel (2026).
What Does Pruning Actually Buy? Memory and Inference Time in Predictive Maintenance Models. Grillmeyer, Daniel; Turhal, Sükrü; Kounev, Samuel (2026).
TRACE-CRC: Trajectory-Adaptive Conformal Risk Control for Multi-Step Channel State Information Prediction. Rezaei, Kiarash; Sattari, Mehdi; Aliakbari, Javad; Svensson, Tommy; Monti, Paolo; Natalino, Carlos (E. Ahlberg; U. Johansson; H. Boström; A. Carlevaro; J. Hallberg Szabadváry; L. Carlsson, eds.) (2026). 329 984–1009.
Reliable prediction of time-varying channel state information (CSI) is essential for efficient wireless communication. Each CSI frame is a matrix-valued representation of the wireless channel response, and a sequence of CSI frames forms a temporal channel trajectory. Modern deep learning-based CSI predictors, however, often provide only point predictions and lack calibrated uncertainty estimates. This limitation is particularly problematic in multi-step CSI prediction, where the target is a sequence of future CSI matrices, and downstream decisions such as beamforming or scheduling may fail if any part of the predicted trajectory is unreliable. We propose trajectory-adaptive calibration and error profiling with conformal risk control (TRACE-CRC), a method for trajectory-aware uncertainty quantification in multi-step CSI prediction. TRACE-CRC constructs Frobenius-norm uncertainty balls around predicted CSI matrices and controls the risk that at least one future frame is uncovered. Instead of calibrating each future step independently, TRACE-CRC combines future-step-dependent error profiling, trajectory difficulty stratification, and learn-then-test (LTT) risk control. Empirically, TRACE-CRC achieves reliable trajectory-level coverage with substantially smaller uncertainty balls than conservative multi-step corrections, while avoiding the trajectory undercoverage of compact stepwise and adaptive conformal base-lines.
LABORATORYINVESTIGATION ONRE-USING POLYETHYLENE(PLASTIC)BAGWASTEMATERIAL FORSOILREINFORCEMENT INGEOTECHNICAL ENGINEERING. Chebet1, F.C.; Kalumba2, D. (F. Chebet1; D. Kalumba2, eds.) (2026).
First record of Andrena melaleuca (Hymenoptera: Andrenidae) in Europe, with notes on Sicily’s role as a gateway to Europe. Zimmermann, Robert; Orr, Michael C.; Korten, Hanno; Wood, Thomas J. (2026). 154 1–8.
Analysis of the Impact of Eight-Bit Reduced Precision on Image Reconstruction Fidelity. Martínez-González, Ricardo Francisco; Rodríguez-León, Abelardo (R. F. Martínez-González, ed.) (2026). 15(2)
This study evaluates the impact of transitioning from FP64 to 8-bit floating-point (FP8 E4M3) for image reconstruction using autoencoders. To address energy and memory constraints in edge computing, we apply Post-Training Quantization with dynamic scaling (range 448). Although quantization increases Mean Squared Error slightly, perceptual quality remains acceptable. Memory use per parameter drops by 87.5%, drastically reducing computational load while preserving utility. The findings confirm that low-precision formats enable efficient AI deployment on resource-limited devices, allowing embedded vision systems to operate with significantly lower energy overhead
Native earthworms and roe deer in temperate forests: Friends in the sun, foes in the shade. Lettenmaier, Ludwig; Eisenhauer, Nico; Cesarz, Simone; Ammer, Christian; Bucharova, Anna; Dittrich, Sebastian; Hausmann, Ronja; Kraus, Daniel; Kölbl, Angelika; Mallick, Soumen; Mamadashvili, Giorgi; Mysterud, Atle; Pierick, Kerstin; Schwarz, Rike; Müller, Jörg; Ristok, Christian (2026). 107(9)
ScrubPIM: Exploiting PIM to Enable In-Memory Error Correction. Christ, Derek; Reith, Tino; Wilbert, Nils; Jung, Matthias (2026). (Vol. 2)
Hunting as anthropogenic sink of biomass or source of carrion? A brief case study based on German hunting bags. Beckmann, Jörg; Müller, Jörg; Horlebein, Sophie; Hoermann, Christian von (2026).
A Systematic Survey on Synthetic Knowledge Graph Generators. Morim da Silva, Ana Alexandra; Röder, Michael; Ngonga Ngomo, Axel-Cyrille (2026).
Management and tree dieback alter beetle assemblage structure and body size distribution in a temperate German forest. Lunow, Julian; Wehner, Katja; Trevisan, Matteo; Blüthgen, Nico; Heethoff, Michael; Müller, Jörg; Simons, Nadja K. (2026).
Contrasting responses of above- and belowground carbon stocks and arthropods in relation to forest management. Lunow, Julian; Pollierer, Melanie M.; Ammer, Christian; Schall, Peter; Scheu, Stefan; Schöning, Ingo; Schrumpf, Marion; Seibold, Sebastian; Weisser, Wolfgang W.; Wöllauer, Stephan; Simons, Nadja K.; Staab, Michael (2026). 16 100482.
Structural characteristics mediate forest mitigation potential against climate change and biodiversity loss. Lunow, Julian; Burrascano, Sabina; Balducci, Lorenzo; Chianucci, Francesco; Chojnacki, Lucas; Doerfler, Inken; Hofmeister, Jeňýk; Hošek, Jan; Ódor, Péter; Schall, Peter; Sitzia, Tommaso; Simons, Nadja K. (2026). 36(2)
An interdisciplinary story-and-simulation approach for assessing forest type changes and shifts in ecosystem service potential. Sacher, Philipp; Mayer, Marius; Job, Hubert; Simons, Nadja (2026). 80(2) 71–90.
Arthropod conservation in roadside verges: Unmown refuges outperform mowing equipment changes. Berger, Johanna L.; Hartlieb, Margarita; Simons, Nadja K.; Blüthgen, Nico (2026). 19(4) 873–883.
Wear Leveling for Byte-Addressable NVM Leveraging a Dual-Stage Address Mapping. Wilbert, Nils; Christ, Derek; Friedl, Ludwig; Jung, Matthias (2026).
Wear Leveling for Byte-Addressable NVM Leveraging a Dual-Stage Address Mapping. Wilbert, Nils; Christ, Derek; Friedl, Ludwig; Jung, Matthias (2026).
Communal Weaving for a Carrier Bag Practice of Computing. Bläsing, Lisa Marie; Horn, Viktoria; Klumbyte, Goda; Lackner, Konstantin; Stöter, Lea; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–3.
Profinite completions and cohomology jump loci. Suciu, Alexander I. (2026, September).
Shifting Stories of Human-Centered Computing Research: Exploring Narratives Through the Lens of Le Guin’s The Carrier Bag Theory of Fiction. Horn, Viktoria; Stöter, Lea; Bläsing, Lisa Marie; Klumbyte, Goda; Lackner, Konstantin; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–4.
Estimated vascular age using the Framingham model as a predictor of metabolic syndrome in a large cohort of Spanish workers. Montero Muñoz, Natalia; Tárraga López, Pedro Juan; Coll Campayo, Irene; López-González, Ángel Arturo; Busquets-Cortés, Carla; Ramírez-Manent, José Ignacio (2026). 73(7) 501773.
BACKGROUND: Vascular age, estimated using the Framingham model, is an intuitive indicator of cardiovascular risk. Metabolic syndrome (MetS) includes several cardiometabolic abnormalities associated with increased morbidity and mortality. The relationship between vascular age and MetS has not been extensively assessed in large working populations. OBJECTIVE: To evaluate the predictive ability of vascular age for identifying MetS in a large cohort of Spanish workers. METHODS: We conducted a cross-sectional study among 336,450 employees aged 18-69 years who underwent standardized occupational health examinations from 2018 to 2022. Vascular age and avoidable lost life years (ALLY) were calculated using the Framingham equation. MetS was defined according to NCEP ATP III, IDF, and Joint Interim Statement (JIS) criteria. Associations were examined using logistic regression models adjusted for sociodemographic and lifestyle variables. Discriminatory performance was assessed through ROC curve analyses. RESULTS: MetS prevalence increased progressively across higher vascular age categories in both sexes. Vascular age demonstrated strong diagnostic performance, with areas under the curvetextgreater0.80 and reaching 0.86 in women according to NCEP ATP III and JIS definitions. Multivariable analyses confirmed independent associations between elevated vascular age and MetS. CONCLUSIONS: Vascular age is a strong and consistent predictor of MetS and represents a practical tool for early cardiometabolic risk detection in occupational settings. Its integration into workplace health surveillance may enhance the identification of high-risk workers and support targeted preventive strategies.
Shifting Stories of Human-Centered Computing Research: Exploring Narratives Through the Lens of Le Guin’s The Carrier Bag Theory of Fiction. Horn, Viktoria; Stöter, Lea; Bläsing, Lisa Marie; Klumbyte, Goda; Lackner, Konstantin; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–4.
The Real Existential Risk Is AI CEOs Avoiding Oversight: “Alternative Nobel” Winner Timnit Gebru. Shaikh, Nermeen; Gebru, Timnit (2026).
We speak to the prominent AI researcher and leading critic of the AI industry, Timnit Gebru, who was recently awarded a 2026 Right Livelihood Award for her work investigating the harms and hype behind the global buildup of artificial intelligence. “Instead of discussing faulty, unreliable systems,” Gebru says tech leaders like SpaceXAI’s Elon Musk, OpenAI’s Sam Altman and Anthropic’s Dario Amodei are “marketing their systems as all-knowing, superpowerful, superintelligent,” and lobbying for “self-policing and self-regulation” to avoid being held “liable through existing laws.” Gebru expresses skepticism over increasingly widespread claims that AI algorithms pose an existential risk to humanity, warning that such claims are overblown and that “what is actually happening is regulatory capture.”
What and Whose Knowledge? Measuring Epistemic Diversity in Large Language Models. Wright, Dustin; Masud, Sarah; Moore, Jared; Yadav, Srishti; Antoniak, Maria; Christensen, Peter Ebert; Park, Chan Young; Augenstein, Isabelle (2026, August).
Large language models (LLMs) are increasingly used as primary knowledge sources, yet their epistemic diversity - defined as the diversity of real-world claims in their outputs - has never been measured. Low epistemic diversity would pose a risk of knowledge collapse as homogeneous LLMs mediate a shrinking in the range of accessible information over time. The dominant paradigm is that overall LLM diversity is low, but this is always with respect to a single point in time, with no reference baseline or consideration for variation across countries. We address this gap in knowledge by performing the first systematic study of epistemic diversity in LLMs across time and cultural context, testing 27 LLMs on 155 topics covering 12 countries, resulting in 1.7M responses and 70M individual claims. We find that epistemic diversity has increased substantially over the past three years, a positive counter to recent diversity pessimism. However, despite progress, we find that every system is less diverse than a search baseline. This gap is not uniform: RAG can improve diversity, while large models are counterintuitively less diverse than smaller ones. Moreover, LLM parametric knowledge systematically reflects English over local-language knowledge for country specific topics. Together, these results demonstrate that while progress on epistemic diversity is tangible, it is insufficient and unevenly distributed.
Narrow Absorption Bands through Exciton Coupling in Supramolecularly Engineered Merocyanine π-Stacks. Bachmann, Paul; Wagenhäuser, Yvonne; Stolte, Matthias; Würthner, Frank (2026).
Simulating Edge Caching and Device-to-Device Mobile Instant Messaging Traffic in Large Urban Areas. Technical Report (Master thesis), Kloth, Ferdinand PhD thesis, University of Würzburg. (2026, September).
Online Decision-Focused Learning under Semi-Bandit Feedback. Dhakal, Aabhash; Lachner, Tim; Mandi, Jayanta; Foschini, Marco; Flath, Christoph Michael (2026).
Online Decision-Focused Learning under Semi-Bandit Feedback. Dhakal, Aabhash; Lachner, Tim; Mandi, Jayanta; Foschini, Marco; Flath, Christoph Michael (2026).
Adiposity-Metabolic Discordance Identifies Cardiometabolically Heterogeneous Profiles in Normal-Weight Adults: A Cross-Sectional Study. González Carrasco, Diego; Tárraga López, Pedro Juan; Piña Dabreu, Mónica Silu; Rodas Cañellas, Lluis; López-González, Ángel Arturo; Ramírez-Manent, José Ignacio (2026). 14(5) 557.
BACKGROUND: Body mass index (BMI) is widely used to classify obesity and cardiometabolic risk, although it may fail to detect hidden metabolic impairment in individuals with normal body weight. Increasing evidence suggests that adiposity and metabolic dysfunction may not always coexist, giving rise to biologically discordant phenotypes associated with different cardiometabolic profiles. METHODS: This cross-sectional study was a secondary analysis of a subset of normal-weight adults selected from a larger database of Spanish workers undergoing routine occupational health examinations between 2019 and 2024. The final analytical sample included 166,008 workers aged 18-69 years with BMI values between 18.5 and 24.9 kg/m2. Participants were classified into four adiposity-metabolic phenotypes according to the presence or absence of increased adiposity, operationally defined as a waist-to-height ratio (WtHR) ≥ 0.50, and metabolic dysfunction, defined as the presence of ≥2 of five adverse cardiometabolic criteria. METS-VF was additionally evaluated as a marker of visceral adiposity. Anthropometric, metabolic, vascular, and lifestyle-related variables were analyzed. Multivariable logistic regression models were used to evaluate factors associated with discordant phenotypes. RESULTS: The concordant healthy phenotype was the most prevalent subgroup (78.9\%), followed by adiposity-only (9.8\%), metabolic-only (9.2\%), and concordant high-risk phenotypes (2.0\%). Despite normal BMI, approximately 21% of participants exhibited adiposity-metabolic discordance or combined high-risk status. The metabolic-only phenotype showed markedly adverse triglyceride, TG/HDL-c ratio, fasting glucose, and blood pressure values despite relatively preserved anthropometric parameters. Conversely, the adiposity-only phenotype exhibited increased central and visceral adiposity with comparatively preserved metabolic status. Sedentary lifestyle, unfavorable dietary adherence, smoking, older age, male sex, and higher BMI within the normal-weight range were independently associated with metabolically adverse phenotypes. The concordant high-risk phenotype demonstrated the greatest overall cardiometabolic burden. CONCLUSIONS: Adults with normal BMI are metabolically heterogeneous and may present clinically relevant hidden-risk phenotypes despite conventional normal-weight classification. Adiposity-metabolic discordance highlights the limitations of BMI-based screening alone and supports the incorporation of multidimensional anthropometric, metabolic, and lifestyle-related assessment strategies for earlier identification of cardiometabolic risk.
Lifestyle and Psychosocial Determinants of Type 2 Diabetes Risk Across Adulthood: The Role of Burnout in a Large Occupational Cohort. Valiente Pizá, Aina Gabriela; Tárraga López, Pedro Juan; López-González, Ángel Arturo; Coll Campayo, Irene; Busquets-Cortés, Carla; Ramírez-Manent, José Ignacio (2026). 14(5) 546.
BACKGROUND: Lifestyle behaviors and psychosocial factors are key determinants of cardiometabolic health across the life course. Beyond traditional risk factors, emerging evidence suggests that chronic stress and burnout may influence metabolic risk through behavioral pathways such as physical inactivity and poor diet. However, their joint contribution to type 2 diabetes risk in working populations remains insufficiently understood. OBJECTIVES: Our objectives were to examine the joint contribution of lifestyle habits, sociodemographic factors, and burnout to type 2 diabetes risk, and to explore potential behavioral pathways linking psychosocial stress to metabolic risk in a large adult population. METHODS: A cross-sectional study was conducted in 92,480 Spanish workers undergoing routine occupational health assessments between 2021 and 2023. Type 2 diabetes risk was assessed using validated tools (FINDRISC, QDScore, CANRISK). Lifestyle indicators included adherence to the Mediterranean diet and physical activity levels; burnout was assessed using the Burnout Assessment Tool (BAT). Multivariable logistic regression models were used to evaluate associations between determinants and diabetes risk. Mediation analyses were performed to assess the contribution of lifestyle behaviors to the association between burnout and diabetes risk, and predictive performance analyses evaluated the incremental value of burnout. RESULTS: Burnout was independently associated with a higher probability of moderate-to-high diabetes risk across all screening tools. Exploratory cross-sectional mediation analyses indicated that lifestyle behaviors, particularly physical inactivity and low adherence to the Mediterranean diet, statistically accounted for approximately 45% of the observed association. Adding burnout to the models significantly improved discrimination and reclassification of moderate-to-high diabetes-risk classification. In addition, higher diabetes risk was consistently observed among individuals from lower socioeconomic groups and those with unhealthy lifestyle profiles. CONCLUSIONS: Lifestyle behaviors and psychosocial stress were associated with estimated diabetes risk across adulthood. Burnout was independently associated with a higher probability of moderate-to-high diabetes-risk classification, with exploratory analyses suggesting that lifestyle behaviors may statistically account for part of this association. These cross-sectional findings highlight the potential relevance of considering both behavioral and psychosocial factors when studying cardiometabolic risk in working populations, while prospective studies are needed to establish temporal and causal relationships.
Technostress and Insulin Resistance Risk: A Cross-Sectional Analysis of 104,175 Spanish Workers Using TyG, TyG-BMI, METS-IR, and SPISE Indices. González Rivas, Marta; López-González, Ángel Arturo; González Carrasco, Diego; Busquets-Cortés, Carla; Vicente-Herrero, María Teófila; Ramírez-Manent, José Ignacio (2026). 14(5) 545.
Background: Technostress has emerged as a growing occupational health concern in increasingly digitalized workplaces. Although its psychological consequences have been extensively investigated, little is known about its potential association with metabolic health and insulin resistance. This study aimed to evaluate the relationship between technostress and insulin resistance risk using four validated surrogate markers in a large cohort of Spanish workers. Methods: A cross-sectional study was conducted among 104,175 Spanish workers who underwent routine occupational health assessments. Technostress was assessed using a 15-item questionnaire covering five technostress dimensions and was analyzed using four operational categories (low, moderate, high, and very high). Insulin resistance risk was assessed using the triglyceride-glucose (TyG) index, TyG-body mass index (TyG-BMI), the metabolic score for insulin resistance (METS-IR), and the single-point insulin sensitivity estimator (SPISE). Sociodemographic characteristics, lifestyle habits, anthropometric measurements, and biochemical parameters were also recorded. Modified Poisson regression with robust variance estimation was used to estimate crude and adjusted prevalence ratios (PRs) for increased insulin resistance risk according to technostress level. Firth penalized logistic regression was additionally performed as a sensitivity analysis to address sparse-data bias and separation. Results: Higher technostress levels were associated with progressively less favorable anthropometric and metabolic profiles. The prevalence of increased insulin resistance risk rose significantly across technostress categories for all markers evaluated (p \textless 0.001). For TyG, prevalence increased from 3.8% in the low technostress group to 54.3% in the very high technostress group. Corresponding increases were observed for TyG-BMI (0.2\% to 78.2\%), METS-IR (0.0\% to 45.2\%), and elevated SPISE-IR values (0.0\% to 57.5\%). After adjustment for age, sex, educational level, physical activity, adherence to the Mediterranean diet, and smoking status, higher technostress remained associated with a higher prevalence of increased insulin resistance risk. A clear graded cross-sectional pattern was observed, with the strongest associations found among workers reporting very high technostress. Conclusions: Higher technostress was associated with a higher prevalence of increased insulin resistance risk according to TyG, the primary outcome, with a clear graded cross-sectional pattern across technostress categories. Associations were also observed for the secondary BMI-containing indices (TyG-BMI, METS-IR, and SPISE-IR), which should be interpreted as complementary rather than independent evidence. Given the cross-sectional design and the pronounced clustering of technostress with adiposity and lifestyle characteristics, residual confounding cannot be excluded and causal inference is not possible.
Optimizing Physical Network Topologies in POBTOG through Edge Addition. Technical Report (Master thesis), Proikakis, Simos PhD thesis, University of Würzburg. (2026, September).
Speculative AI Futures Workshop. Lackner, Konstantin; Stöter, Lea; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–4.
Healthy Lifestyle Behaviors and Technostress: A Combined Lifestyle Score Analysis in 104,175 Spanish Workers. González Rivas, Marta; López-González, Ángel Arturo; González Carrasco, Diego; Busquets-Cortés, Carla; Rodas Cañellas, Lluis; Ramírez-Manent, José Ignacio (2026). 18(17) 2754.
Background: Technostress has emerged as a major occupational health concern in increasingly digitalized workplaces. Although organizational and technological determinants of technostress have been widely investigated, the potential influence of healthy lifestyle behaviors remains poorly understood. This study aimed to evaluate the association between a combined Healthy Lifestyle Score (HLS) and technostress in a large cross-sectional sample of Spanish workers. Methods: A cross-sectional study was conducted among 104,175 workers who underwent routine occupational health examinations between January 2021 and December 2024. The Healthy Lifestyle Score was constructed by assigning one point each for regular physical activity, high adherence to the Mediterranean diet, and non-smoking status, resulting in scores ranging from 0 to 3. Technostress was assessed using the Technostress Short Questionnaire (TCS-Short) and categorized as low, moderate, high, or very high. Logistic regression models were used to estimate crude and adjusted odds ratios (ORs) and 95% confidence intervals (CIs) for high-to-very high technostress according to HLS categories. Results: Significant differences in technostress levels were observed across HLS categories (p \textless 0.001). The prevalence of high-to-very high technostress was 50.8% among workers with HLS = 0 and 50.7% among those with HLS = 1, decreasing markedly to 7.5% and 7.2% among workers with HLS = 2 and HLS = 3, respectively. After adjustment for sex, age, educational level, and social class, participants with HLS = 2 and HLS = 3 exhibited substantially lower odds of high technostress (OR = 0.073, 95\% CI 0.068-0.078 and OR = 0.074, 95\% CI 0.069-0.079, respectively) compared with those with HLS = 0. The categorical analysis suggested a threshold-like rather than progressive association, with substantially lower odds of high-to-very high technostress observed among workers with HLS = 2 and HLS = 3, whereas HLS = 1 did not show lower odds compared with HLS = 0. The final model demonstrated excellent discrimination (AUC = 0.902). Conclusions: Healthy lifestyle profiles were strongly associated with technostress in this large cross-sectional occupational sample. Workers with HLS = 2 and HLS = 3 showed markedly lower odds of high-to-very high technostress than those with HLS = 0, whereas HLS = 1 did not show lower odds. Component-specific analyses indicated that the associations differed substantially across the behaviors comprising the score, supporting interpretation of the HLS as an unweighted behavioral count rather than as a measure of equivalent contributions from each component.
Evolution of functional and mental status and quality of life in people aged 75 years and over after the COVID-19 pandemic in Spain: a prospective cohort study. Esteban-Sepúlveda, Silvia; Pascual-Garcia, Marcos; Blanco, Joan; Sánchez-Ruano, Raquel; Cervera, Ana Mateo; Moreno, Maria Angeles Cidoncha; Vidal-Thomas, Maria-Clara; Company-Sancho, María Consuelo; Feria-Raposo, Isabel; Casbas, Mayte Moreno; Cameselle-Lago, Candela; Artiques, Eva; Padilla, Jorge; Bernabéu, Clara; Group, Cuidamos+75; Rico-Blázquez, Milagros (2026). 26(1) 1136.
The COVID-19 pandemic has had significant health and psychosocial consequences in the older adults. However, there is little community-based evidence that clearly distinguishes the effect attributable to SARS-CoV-2 infection to be differentiated from the contextual impact of the pandemic itself. The objective of this study was to describe the 18-month evolution of multidimensional domains of comprehensive geriatric assessment and to compare trajectories according to the presence or absence of confirmed infection at the start of follow-up. Methods A prospective, multicenter cohort study was conducted in primary care across 11 Spanish regions. Non-institutionalized individuals aged 75 years and over recruited by trained nurses were included. Comprehensive geriatric assessments were performed at baseline and at 6, 12, and 18 months, including functional status, emotional state, nutritional risk, social support, and health-related quality of life. Exposure: confirmed SARS-CoV-2 infection documented by RT-PCR and/or rapid antigen testing recorded in the electronic health record from May 2020 until the time of inclusion in the study. Longitudinal trajectories and exposure time interactions were analyzed using linear mixed-effects models adjusted for relevant covariates, with sensitivity analyses based on complete-case analyses restricted to participants with complete follow-up. Results A total of 1,072 participants were included at baseline. In the overall cohort, there were significant time effects indicating gradual worsening in most domains (functional capacity, nutritional status, social support, and quality of life). Trajectories were generally parallel between infected and uninfected individuals, with no consistent exposure time interactions, except for anxiety (p = 0.043), which showed a differential pattern over time. Sensitivity analyses confirmed the robustness of the findings. Conclusions In non-institutionalized adults aged 75 years or older, we observed a slight, progressive decline in overall health during the post-pandemic period, generally unrelated to prior COVID-19. Trajectories were similar between exposed and unexposed individuals, with the exception of anxiety, which showed a differential course by exposure status, underscoring the need for targeted monitoring of emotional health after infection. Public health responses to health or social crises should prioritize functional autonomy, social support, and mental health to preserve quality of life in this population.
Atherogenic Risk in Commerce and Industry Workers: Associations with Sociodemographic and Lifestyle Factors in a Large Spanish Occupational Cohort. Fernández-Figares Vicioso, María Pilar; Vicente-Herrero, María Teófila; Sbert, Pere Riutord; Ramírez-Manent, José Ignacio; Tárraga Marcos, Pedro Juan; Del Barrio Fernández, José Luis; López-González, Ángel Arturo (2026). 38(5) 500873.
BACKGROUND: Atherogenic dyslipidemia (AD) and associated lipid ratios are critical markers for cardiovascular risk, yet little is known about how these markers vary by occupational sector and sociodemographic or lifestyle factors in working populations. OBJECTIVE: To evaluate the prevalence and determinants of elevated atherogenic risk according to total cholesterol/HDL-c (TC/HDL-c), LDL-c/HDL-c, triglycerides/HDL-c (TG/HDL-c), and AD in workers from the commerce and industry sectors, stratified by sex, age, education, physical activity, diet, and smoking. METHODS: This cross-sectional study included 56,856 Spanish workers (39,448 men and 17,408 women) from commerce (n=27,448) and industry (n=29,408). Sociodemographic, clinical, and lifestyle data were collected, and atherogenic risk was assessed using TC/HDL-c, LDL-c/HDL-c, TG/HDL-c ratios, and AD presence. Mean values and prevalence were compared by group, and multinomial logistic regression was used to estimate the association between risk markers and covariates. RESULTS: Workers in the industry sector showed higher mean values and prevalence of all atherogenic risk scales compared to those in commerce, particularly among men and older age groups. Male sex, older age, lower education, physical inactivity, absence of Mediterranean diet, and smoking were consistently associated with higher odds of elevated lipid ratios and AD. Notably, the absence of physical activity was strongly associated with all outcomes, with ORs ranging from 3.08 to 11.66. The industrial sector was independently associated with increased risk: TC/HDL-c (OR=1.23), LDL-c/HDL-c (OR=1.15), TG/HDL-c (OR=1.16), and AD (OR=1.19). CONCLUSIONS: Atherogenic risk profiles are less favorable among industrial workers and are significantly influenced by modifiable lifestyle factors. These findings support the need for preventive strategies tailored to the occupational context, with emphasis on promoting physical activity, smoking cessation, and healthier dietary habits, in order to reduce cardiovascular risk in these populations.
Crossing the Threshold: Using Photostationary States to Control Supramolecular Polymerisation. George, Deepu; Wu, Jiarong; Greb, Leo; Stepanenko, Vladimir; Izuagbe, Aidan; Nuhn, Lutz; Würthner, Frank; Greenfield, Jake L. (2026).
Continuum theory for topological phase transitions in exciton systems. Cai, Xiaochan; Consiglio, Armando; Di Sante, Domenico; Thomale, Ronny; Hanke, Werner (2026). 113(20) 205121.
TRRAP enables MMB-dependent mitotic transcription and determines sensitivity to CHK1 inhibition. Liss, Franziska; Gertzmann, Dörthe; Murugan, Devi Bala; Bohn, Leonie; Brethauer, Wiebke; Kuhn, Phil; Wenzel, Lara; Hopff, Ann-Sophie; Schülein-Völk, Christina; Ade, Carsten P.; Weinstock, Grit; Wolf, Elmar; Eilers, Martin; von Eyss, Björn; Gaubatz, Stefan (2026). 45(9) 117985.
Speculative AI Futures Workshop. Lackner, Konstantin; Stöter, Lea; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–4.
Speculative AI Futures Workshop. Lackner, Konstantin; Stöter, Lea; Draude, Claude in NordiCHI ’26 Adjunct (2026). 1–4.
A Case Study on the Value of Simulated and Synthetic Microservice Applications for Performance Model Training. Lubas, Yannik; Straesser, Martin; Rohwer, Ivo; Bauer, André; Kounev, Samuel A. Herrmann (ed.) (2025). (Vol. 45) 35–37.
Microservices have become a central architectural style for cloud-based systems, driving increased interest in their performance characteristics. However, the limited availability of real-world microservice applications for academic research constrains empirical studies in this area, particularly those using application-agnostic, machine learning-based approaches. Prior work has explored synthetic generation and simulation as alternative means of obtaining performance data; however, their benefits when used alongside real-world measurements are less understood. Using the saturation predictor Monitorless in a case study, we evaluate two scenarios. Our results indicate that generated and simulated applications improve predictive performance on previously unseen, real-world systems. In our case, generated applications reduced false positives, simulated applications enhanced robustness, while their combination yielded the most balanced predictor. The findings suggest that synthetic and simulated applications can effectively complement real-world data, enabling more diverse and robust evaluation of performance models.
Enabling efficient analysis of biobank-scale data with genotype representation graphs. DeHaas, Drew; Pan, Ziqing; Wei, Xinzhu (2025). 5(2) 112–124.
Computational analysis of a large number of genomes requires a data structure that can represent the dataset compactly while also enabling efficient operations on variants and samples. However, encoding genetic data in existing tabular data structures and file formats has become costly and unsustainable. Here we introduce the genotype representation graph (GRG), a fully connected hierarchical data structure that losslessly encodes phased whole-genome polymorphisms. Exploiting variant-sharing across samples enables GRG to compress 200,000 UK Biobank phased human genomes to 5--26thinspacegigabytes per chromosome, also enabling graph-traversal algorithms to reuse computed values in random access memory. Constructing and processing GRG files scales to a million whole genomes. Using allele frequencies and association effects as examples, we show that computation on GRG via graph traversal runs the fastest among all tested alternatives. GRG-based algorithms have the potential to increase the scalability and reduce the cost of analyzing large genomic datasets.
Analysis-ready VCF at Biobank scale using Zarr. Czech, Eric; Tyler, Will; White, Tom; Jeffery, Ben; Millar, Timothy R; Elsworth, Benjamin; Guez, Jérémy; Hancox, Jonny; Karczewski, Konrad J; Miles, Alistair; Tallman, Sam; Unneberg, Per; Wojdyla, Rafal; Zabad, Shadi; Hammerbacher, Jeff; Kelleher, Jerome (2025). 14 giaf049.
Variant Call Format (VCF) is the standard file format for interchanging genetic variation data and associated quality control metrics. The usual row-wise encoding of the VCF data model (either as text or packed binary) emphasizes efficient retrieval of all data for a given variant, but accessing data on a field or sample basis is inefficient. The Biobank-scale datasets currently available consist of hundreds of thousands of whole genomes and hundreds of terabytes of compressed VCF. Row-wise data storage is fundamentally unsuitable and a more scalable approach is needed.Zarr is a format for storing multidimensional data that is widely used across the sciences, and is ideally suited to massively parallel processing. We present the VCF Zarr specification, an encoding of the VCF data model using Zarr, along with fundamental software infrastructure for efficient and reliable conversion at scale. We show how this format is far more efficient than standard VCF-based approaches, and competitive with specialized methods for storing genotype data in terms of compression ratios and single-threaded calculation performance. We present case studies on subsets of 3 large human datasets (Genomics England: \\($n\$\)=78,195; Our Future Health: \\($n\$\)=651,050; All of Us: \\($n\$\)=245,394) along with whole genome datasets for Norway Spruce (\\($n\$\)=1,063) and SARS-CoV-2 (\\($n\$\)=4,484,157). We demonstrate the potential for VCF Zarr to enable a new generation of high-performance and cost-effective applications via illustrative examples using cloud computing and GPUs.Large row-encoded VCF files are a major bottleneck for current research, and storing and processing these files incurs a substantial cost. The VCF Zarr specification, building on widely used, open-source technologies, has the potential to greatly reduce these costs, and may enable a diverse ecosystem of next-generation tools for analysing genetic variation data directly from cloud-based object stores, while maintaining compatibility with existing file-oriented workflows.
Pareto-Informed Smart "Predict, then Optimize" for Multi-Objective Combinatorial Problems. Dhakal, Aabhash; Lachner, Tim (2025).
Dynamic SDN Controller Placement based on Deep Reinforcement Learning. Shen, Fan (Deutscher_Gewerkschaftsbund_(DGB), ed.) (2023).
Die IG Metall schlage eine Vier-Tage-Woche vor - und spreche lediglich "von einem gewissen Lohnausgleich". Ist das realistisch? Arbeitsreduzierung habe schon einmal gut bei fast vollem Lohnausgleich funktioniert: bei VW. Vor 25 Jahren habe die Vier-Tage-Woche Arbeitsplätze gerettet und die Lebensqualität verbessert.
Vier Tage sind eine Woche. Gesterkamp, Thomas Deutscher_Gewerkschaftsbund_(DGB) (ed.) (2020).
Die IG Metall schlage eine Vier-Tage-Woche vor - und spreche lediglich "von einem gewissen Lohnausgleich". Ist das realistisch? Arbeitsreduzierung habe schon einmal gut bei fast vollem Lohnausgleich funktioniert: bei VW. Vor 25 Jahren habe die Vier-Tage-Woche Arbeitsplätze gerettet und die Lebensqualität verbessert.
System Analysis and Design for a Business Development Management System Based on Saudi Arabia Market. Deutscher_Gewerkschaftsbund_(DGB) (2017).
Die IG Metall schlage eine Vier-Tage-Woche vor - und spreche lediglich "von einem gewissen Lohnausgleich". Ist das realistisch? Arbeitsreduzierung habe schon einmal gut bei fast vollem Lohnausgleich funktioniert: bei VW. Vor 25 Jahren habe die Vier-Tage-Woche Arbeitsplätze gerettet und die Lebensqualität verbessert.
SECURITY VIGILANCE SYSTEM THROUGH LEVEL DRIVEN SECURITY MATURITY MODEL. Pandey, S. K. (2012). 2(2) 11–17.
Success of any software system largely looms upon its vigilance efficiency that prompts organizations to meet the set of objectives in the arena of networks. In the highly competitive world, everything appears to be vulnerable; information system is also not an exception to this fact. The security of information system has become a cause of great concern. On the contrary, till time the software security engineers are trying hard to develop fully protected and highly secured information systems but all these developments are at nascent stages. It is quite revelling that in the earlier research studies, little attention is paid to highlight an accurate status of the security alertness for developed software. Hence, keeping all these factors at the backdrop, this paper is an attempt to propose a holistic Security Maturity Model (SMM), in which five levels/stars have been developed, driven on the strength of the security vigilance occurring at the various stages for any software. SMM is in its conceptual stage; the detailed steps will certainly require time to be developed so that every software system can reap out the benefits of this model. To categorize/discriminate the level of potency, SMM will be highlighted through appropriate ranking/star system. It is hoped that if SMM will be followed in its true letter and sprit; undoubtedly, this will restore the clients’ trust and confidence on the software as well as their corresponding vendors. Moreover, this will also enable software industry to follow transparent and ethical practices.
Dorfbezogene Ökomaßnahmen autochthoner Gruppen (Six-S) in Burkina Faso. Schoop, Wolfgang M. Bollig, F. Klees (eds.) (1994). 361–367.
Nomadenfrauen in der Dürre – Das Beispiel der Mahria Kamelnomaden (Nördliche Rizeigat) in Norddarfur/Sudan. Holter, Uta M. Bollig, F. Klees (eds.) (1994). 255–273.
Wildpflanzen als Ressourcen in unterschiedlichen ökonomischen und ökologischen Systemen in Ostafrika. Esser, Monika; Esser, Otto M. Bollig, F. Klees (eds.) (1994). 187–226.
Desertifikation in Afrika – Ein ungelöstes ökologisches Problem. Mensching, Horst G. M. Bollig, F. Klees (eds.) (1994). 29–46.
Die Repräsentation von Krisen in traditionellen Prosatexten afrikanischer Erzähler bzw. Autoren. Möhlig, Wilhelm J.G. M. Bollig, F. Klees (eds.) (1994). 275–287.
Nutzung peripherer Wirtschaftsräume in Namibia, Okavango und Caprivi. Schneider, Karl-Günther M. Bollig, F. Klees (eds.) (1994). 345–360.
The Pathways of the Past: !Kung San Hxaro Exchange and History. Wiessner, Polly M. Bollig, F. Klees (eds.) (1994). 101–124.
Vorwort. Kuper, Rudolph M. Bollig, F. Klees (eds.) (1994). 9–10.
Einführung: Die “afrikanische Krise” – Medien, Wissenschaft und die afrikanische Perspektive. Bollig, Michael; Klees, Frank M. Bollig, F. Klees (eds.) (1994). 11–28.
Milchverarbeitung und Nahrungsmittelknappheit bei afrikanischen Pastoralisten. Casimir, Michael J.; Bollig, Michael M. Bollig, F. Klees (eds.) (1994). 227–253.
Der altägyptische Staat und dezentralisiertes Krisenmanagement. Müller-Wollermann, Renate M. Bollig, F. Klees (eds.) (1994). 317–323.
Futterressourcen in der Butana (Rep. Sudan): Zur Problematik der Dynamik ökologischer Tragfähigkeit. Pflaumbaum, Holger M. Bollig, F. Klees (eds.) (1994). 67–80.
“Zu wenig Chalzedon” – Kritischer Rohstoffmangel bei prähistorischen Wildbeutern in Namibia. Richter, Jürgen M. Bollig, F. Klees (eds.) (1994). 179–186.
Krisenmanagement und Risikominimierung bei den pastoralnomadischen Pokot Nordwestkenias. Bollig, Michael M. Bollig, F. Klees (eds.) (1994). 125–157.
Staatlich verordneter “self-help spirit” versus lokale “self-reliance”: Regionale Kulturfestivals in Ghana als politische Arenen. Lentz, Carola M. Bollig, F. Klees (eds.) (1994). 293–316.
“Der Boden ist meine Haut!” Zur Lebenssituation der Bauern in der oberägyptischen Provinz Qena. Weier, Michael M. Bollig, F. Klees (eds.) (1994). 325–343.
Hungersnöte: Erkundungen zu den demographischen Folgen von Katastrophen. Lang, Hartmut M. Bollig, F. Klees (eds.) (1994). 81–100.
Wirtschaftsweisen im Neolithikum der Ostsahara und ihr Einfluß auf die Vegetation. Neumann, Katharina M. Bollig, F. Klees (eds.) (1994). 47–65.
Anschriften der Autoren. Bollig, Michael; Klees, Frank M. Bollig, F. Klees (eds.) (1994). 376.
Sprache und Krisenmanagement – Überlegungen zur Konzeptualisierung von Krisen bei südafrikanischen Wildbeutern. Voßen, Rainer M. Bollig, F. Klees (eds.) (1994). 289–292.
Ressourcensicherung – Armutsbekämpfung: einheimische Konzepte und entwicklungspolitische Konzeptionen. Trittler, Bertold M. Bollig, F. Klees (eds.) (1994). 369–375.
Wirtschaftliche und soziale Stabilisierungsstrategien südäthiopischer Feldbauern. Amborn, Hermann M. Bollig, F. Klees (eds.) (1994). 159–177.